README.md
| 1 | --- |
| 2 | license: mit |
| 3 | tags: |
| 4 | - vision |
| 5 | - image-segmentation |
| 6 | datasets: |
| 7 | - huggan/cityscapes |
| 8 | widget: |
| 9 | - src: https://huggingface.co/datasets/shi-labs/oneformer_demo/blob/main/cityscapes.png |
| 10 | example_title: Cityscapes |
| 11 | --- |
| 12 | |
| 13 | # OneFormer |
| 14 | |
| 15 | OneFormer model trained on the Cityscapes dataset (large-sized version, Swin backbone). It was introduced in the paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) by Jain et al. and first released in [this repository](https://github.com/SHI-Labs/OneFormer). |
| 16 | |
| 17 |  |
| 18 | |
| 19 | ## Model description |
| 20 | |
| 21 | OneFormer is the first multi-task universal image segmentation framework. It needs to be trained only once with a single universal architecture, a single model, and on a single dataset, to outperform existing specialized models across semantic, instance, and panoptic segmentation tasks. OneFormer uses a task token to condition the model on the task in focus, making the architecture task-guided for training, and task-dynamic for inference, all with a single model. |
| 22 | |
| 23 | 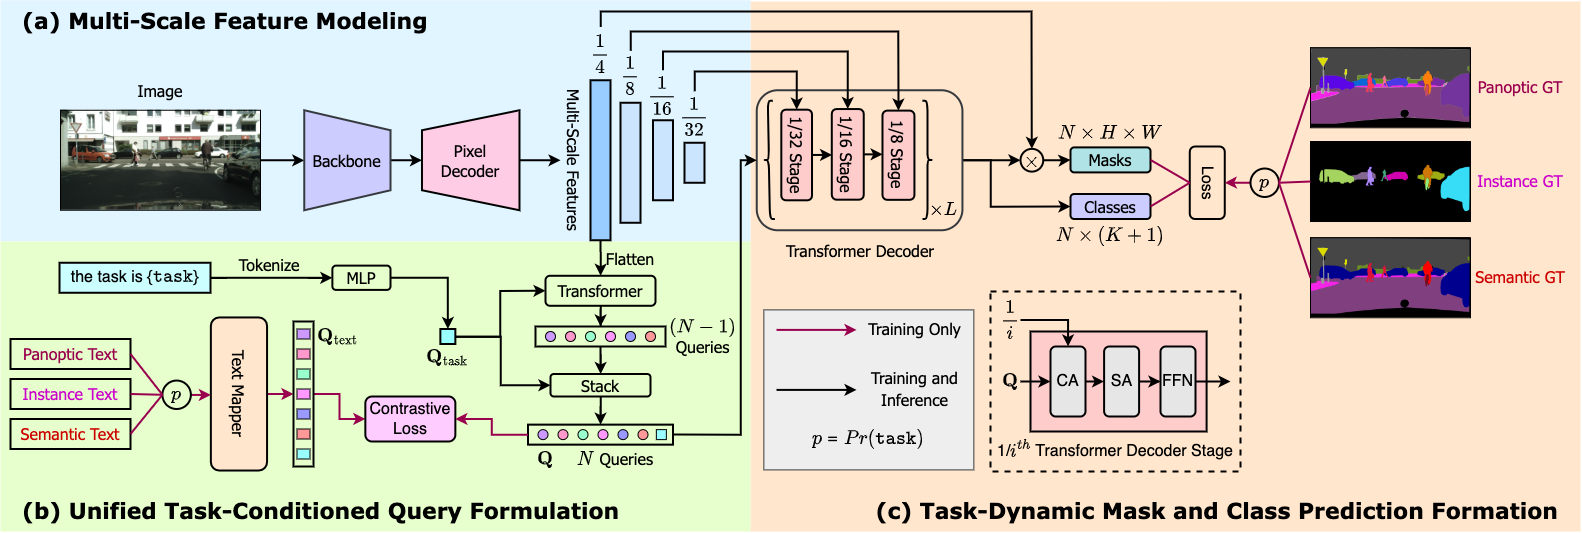 |
| 24 | |
| 25 | ## Intended uses & limitations |
| 26 | |
| 27 | You can use this particular checkpoint for semantic, instance and panoptic segmentation. See the [model hub](https://huggingface.co/models?search=oneformer) to look for other fine-tuned versions on a different dataset. |
| 28 | |
| 29 | ### How to use |
| 30 | |
| 31 | Here is how to use this model: |
| 32 | |
| 33 | ```python |
| 34 | from transformers import OneFormerProcessor, OneFormerForUniversalSegmentation |
| 35 | from PIL import Image |
| 36 | import requests |
| 37 | url = "https://huggingface.co/datasets/shi-labs/oneformer_demo/blob/main/cityscapes.png" |
| 38 | image = Image.open(requests.get(url, stream=True).raw) |
| 39 | |
| 40 | # Loading a single model for all three tasks |
| 41 | processor = OneFormerProcessor.from_pretrained("shi-labs/oneformer_cityscapes_swin_large") |
| 42 | model = OneFormerForUniversalSegmentation.from_pretrained("shi-labs/oneformer_cityscapes_swin_large") |
| 43 | |
| 44 | # Semantic Segmentation |
| 45 | semantic_inputs = processor(images=image, task_inputs=["semantic"], return_tensors="pt") |
| 46 | semantic_outputs = model(**semantic_inputs) |
| 47 | # pass through image_processor for postprocessing |
| 48 | predicted_semantic_map = processor.post_process_semantic_segmentation(outputs, target_sizes=[image.size[::-1]])[0] |
| 49 | |
| 50 | # Instance Segmentation |
| 51 | instance_inputs = processor(images=image, task_inputs=["instance"], return_tensors="pt") |
| 52 | instance_outputs = model(**instance_inputs) |
| 53 | # pass through image_processor for postprocessing |
| 54 | predicted_instance_map = processor.post_process_instance_segmentation(outputs, target_sizes=[image.size[::-1]])[0]["segmentation"] |
| 55 | |
| 56 | # Panoptic Segmentation |
| 57 | panoptic_inputs = processor(images=image, task_inputs=["panoptic"], return_tensors="pt") |
| 58 | panoptic_outputs = model(**panoptic_inputs) |
| 59 | # pass through image_processor for postprocessing |
| 60 | predicted_semantic_map = processor.post_process_panoptic_segmentation(outputs, target_sizes=[image.size[::-1]])[0]["segmentation"] |
| 61 | ``` |
| 62 | |
| 63 | For more examples, please refer to the [documentation](https://huggingface.co/docs/transformers/master/en/model_doc/oneformer). |
| 64 | |
| 65 | ### Citation |
| 66 | |
| 67 | ```bibtex |
| 68 | @article{jain2022oneformer, |
| 69 | title={{OneFormer: One Transformer to Rule Universal Image Segmentation}}, |
| 70 | author={Jitesh Jain and Jiachen Li and MangTik Chiu and Ali Hassani and Nikita Orlov and Humphrey Shi}, |
| 71 | journal={arXiv}, |
| 72 | year={2022} |
| 73 | } |
| 74 | ``` |
| 75 | |